tidymatrix wraps the standard R functions for principal component
analysis (prcomp()), hierarchical clustering
(hclust()) and k-means (kmeans()). Each
analysis runs along the active dimension and does two things:
- it adds its per-row or per-column results (PC scores, cluster labels) to the active metadata, where they can be filtered, grouped and plotted like any other variable, and
- it stores the full result object, which you can retrieve with
get_analysis().
library(tidymatrix)
library(dplyr, warn.conflicts = FALSE)
Data
We use the big5 personality survey (see
?big5), with careless respondents removed and reverse-keyed
items re-scored so that a high value always means a high trait level.
The Matrix operations vignette
explains these steps.
tm <- tidymatrix(big5_responses, big5_respondents, big5_items) |>
  activate(rows) |>
  filter(completion_min > 3.5) |>
  transform_matrix(\(x, flip) ifelse(flip, 6L - x, x), flip = reversed)

tm
#> # A tidymatrix: 388 x 30 matrix
#> # Active: rows
#> #
#> # Row data: 388 rows x 8 columns
#> # Column data: 30 rows x 5 columns
#> #
#> # Active data (rows):
#>   respondent_id age gender education     occupation country life_satisfaction
#> 1          R001  52 Female Secondary Service/Manual      EE                 8
#> 2          R002  32 Female    Master         Office      FI                 4
#> 3          R003  66   Male  Bachelor         Office      EE                 6
#> 4          R004  42   Male  Bachelor   Professional      EE                 9
#> 5          R005  48 Female Secondary         Office      FI                 8
#> 6          R006  62 Female     Basic Service/Manual      EE                 4
#>   completion_min
#> 1           19.8
#> 2            6.2
#> 3            6.3
#> 4            9.7
#> 5           14.2
#> 6           11.6
PCA
Which way?
The active component decides what the observations are:
-
activate(rows): respondents are the observations and items the variables. Each respondent gets PC scores; the loadings describe the items. -
activate(columns): items are the observations and respondents the variables. Each item gets coordinates in PC space.
PCA on respondents
tm <- tm |>
  activate(rows) |>
  compute_prcomp(n_components = 5)

tm |>
  activate(rows) |>
  select(respondent_id, row_pca_PC1:row_pca_PC5)
#> # A tidymatrix: 388 x 30 matrix
#> # Active: rows
#> #
#> # Row data: 388 rows x 6 columns
#> # Column data: 30 rows x 5 columns
#> #
#> # Active data (rows):
#>      respondent_id row_pca_PC1 row_pca_PC2 row_pca_PC3 row_pca_PC4 row_pca_PC5
#> R001          R001   2.0329689  -0.2312498  -2.1412583   0.1924756  2.00705455
#> R002          R002   2.5004478   2.6842796   2.3221050  -1.1672864 -1.04262340
#> R003          R003   2.1131131  -3.1613248  -0.8710424   0.2558892  0.60512373
#> R004          R004   2.1817306   1.9286341   1.3764986  -1.3258180 -0.68187279
#> R005          R005  -0.7987357  -3.8207033   4.7528449   0.1305124  1.06946424
#> R006          R006   5.1128660  -2.7926437   2.0634259   2.7473609 -0.09283606
n_components limits how many score columns are added to
the metadata; the stored prcomp object always has all of
them. Arguments such as center and scale. are
passed on to prcomp().
pca <- get_analysis(tm, "row_pca")
round(summary(pca)$importance[, 1:7], 3)
#>                          PC1   PC2   PC3   PC4   PC5   PC6   PC7
#> Standard deviation     2.626 2.208 2.065 1.899 1.771 1.034 1.004
#> Proportion of Variance 0.173 0.122 0.107 0.090 0.079 0.027 0.025
#> Cumulative Proportion  0.173 0.295 0.402 0.492 0.571 0.597 0.623
Five components stand out, one for each trait. The loadings are the
rotation element of the prcomp object, with
one row per item. Adding them to the item metadata makes them easy to
inspect:
tm <- tm |>
  activate(columns) |>
  mutate(
    loading_PC1 = pca$rotation[item_id, "PC1"],
    loading_PC2 = pca$rotation[item_id, "PC2"]
  )

tm |>
  activate(columns) |>
  as_tibble() |>
  group_by(trait) |>
  summarise(across(c(loading_PC1, loading_PC2), mean))
#> # A tibble: 5 × 3
#>   trait             loading_PC1 loading_PC2
#>   <chr>                   <dbl>       <dbl>
#> 1 Agreeableness         -0.105      -0.0459
#> 2 Conscientiousness     -0.252      -0.0559
#> 3 Extraversion          -0.0623      0.179
#> 4 Neuroticism            0.274       0.100
#> 5 Openness              -0.103       0.341
As usual for PCA, each component mixes several traits. The PC scores can be related to anything in the respondent metadata:
PCA on items
With columns active, the items are placed in the space spanned by the respondents. Items of the same trait end up close to each other:
tm <- tm |>
  activate(columns) |>
  compute_prcomp(n_components = 2)

tm |>
  activate(columns) |>
  as_tibble() |>
  group_by(trait) |>
  summarise(
    PC1 = mean(column_pca_PC1),
    PC2 = mean(column_pca_PC2)
  )
#> # A tibble: 5 × 3
#>   trait                PC1   PC2
#>   <chr>              <dbl> <dbl>
#> 1 Agreeableness      -1.16 12.6
#> 2 Conscientiousness -12.6  -1.85
#> 3 Extraversion       -1.34 -6.61
#> 4 Neuroticism        16.3  -2.65
#> 5 Openness           -1.28 -1.49
The Plotting and exporting vignette plots this.
Hierarchical clustering
compute_hclust() computes a distance matrix with
dist(), clusters it with hclust() and, if
k or h is given, cuts the tree and stores the
cluster labels in {name}_cluster.
Clustering items
Do the answers alone reveal which items belong together?
tm <- tm |>
  activate(columns) |>
  compute_hclust(k = 5, method = "ward.D2", name = "item_clusters")

tm |>
  activate(columns) |>
  as_tibble() |>
  count(trait, item_clusters_cluster)
#> # A tibble: 5 × 3
#>   trait             item_clusters_cluster     n
#>   <chr>             <fct>                 <int>
#> 1 Agreeableness     2                         6
#> 2 Conscientiousness 3                         6
#> 3 Extraversion      1                         6
#> 4 Neuroticism       4                         6
#> 5 Openness          5                         6
Each cluster corresponds to exactly one trait. The dendrogram is the
stored hclust object:
hc <- get_analysis(tm, "item_clusters")
plot(hc, main = "Items", xlab = "", sub = "")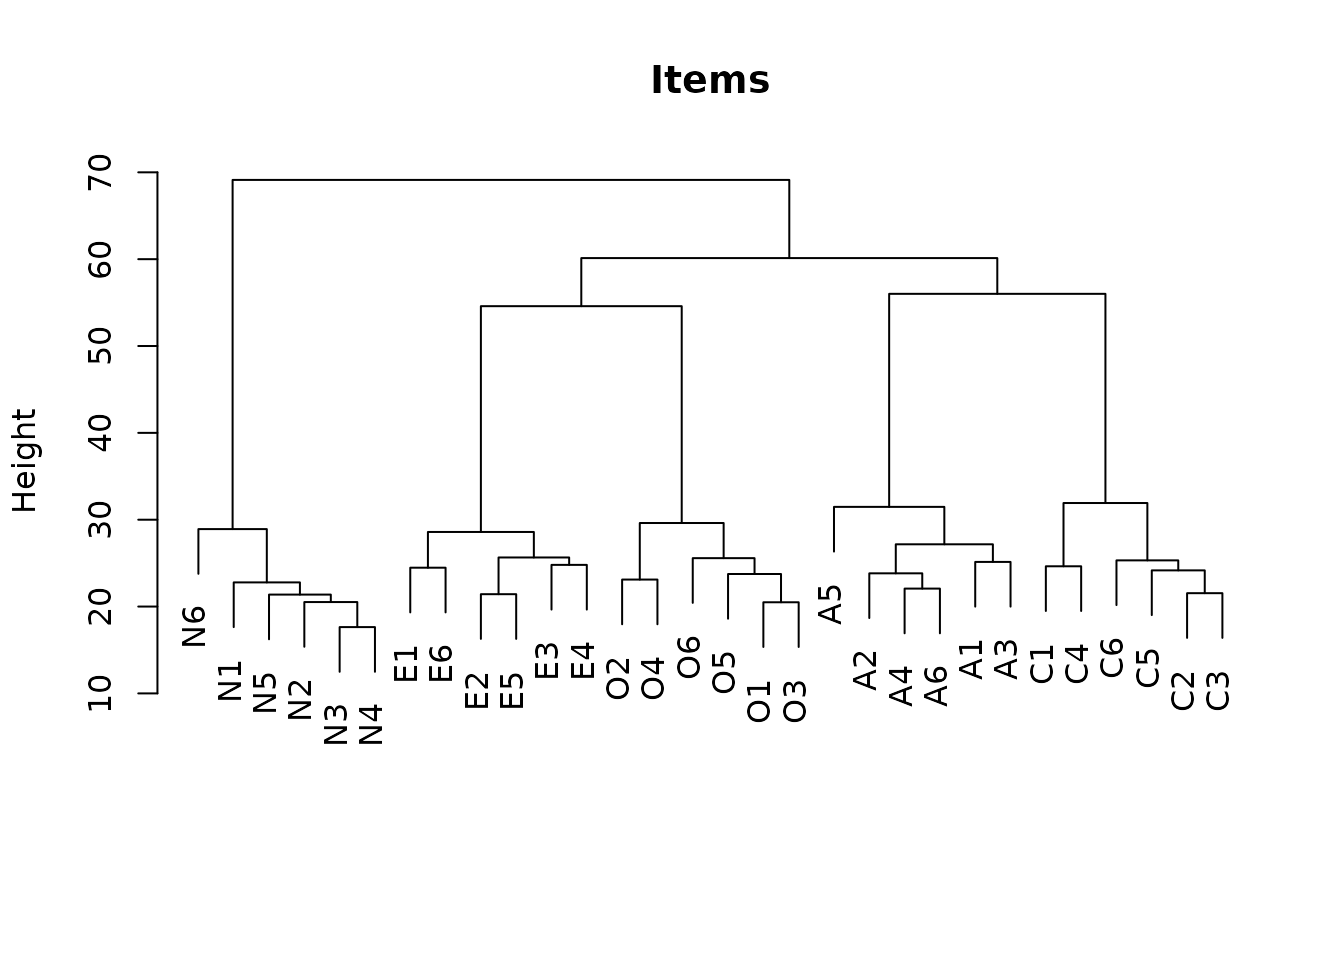
This only works because the reverse-keyed items have been re-scored. On the raw answers, “I keep in the background” is far from “I start conversations” even though both measure extraversion:
tidymatrix(big5_responses, big5_respondents, big5_items) |>
  activate(rows) |>
  filter(completion_min > 3.5) |>
  activate(columns) |>
  compute_hclust(k = 5, method = "ward.D2") |>
  as_tibble() |>
  count(trait, column_hclust_cluster)
#> # A tibble: 10 × 3
#>    trait             column_hclust_cluster     n
#>    <chr>             <fct>                 <int>
#>  1 Agreeableness     2                         2
#>  2 Agreeableness     3                         4
#>  3 Conscientiousness 2                         2
#>  4 Conscientiousness 4                         4
#>  5 Extraversion      1                         4
#>  6 Extraversion      2                         2
#>  7 Neuroticism       2                         4
#>  8 Neuroticism       4                         2
#>  9 Openness          2                         2
#> 10 Openness          5                         4
method is passed to hclust() and
dist_method to dist(). Further arguments go to
dist().
Clustering respondents
Clustering the respondents works the same way with rows active:
tm <- tm |>
  activate(rows) |>
  compute_hclust(k = 4, method = "ward.D2", name = "resp_hclust")

tm |>
  activate(rows) |>
  as_tibble() |>
  count(resp_hclust_cluster)
#> # A tibble: 4 × 2
#>   resp_hclust_cluster     n
#>   <fct>               <int>
#> 1 1                      63
#> 2 2                     134
#> 3 3                      84
#> 4 4                     107
(Counting on the tidymatrix itself,
count(resp_hclust_cluster), would also aggregate the
matrix, and so drop the stored analyses; see below.)
k-means
compute_kmeans() wraps kmeans(); arguments
like nstart and iter.max are passed on.
set.seed(42)
tm <- tm |>
  activate(rows) |>
  compute_kmeans(centers = 3, nstart = 25, name = "resp_kmeans")

km <- get_analysis(tm, "resp_kmeans")
km$size
#> [1] 126 137 125
Profiling clusters
Cluster labels are ordinary metadata, so the grouping machinery from
the Working with rows and columns
vignette turns them into a cluster × trait profile: average the
respondents within each cluster, then the items within each trait.
Summarising replaces the respondents with clusters, so the stored
analyses no longer fit the data and are dropped with a warning;
tm itself is unchanged.
profile <- tm |>
  activate(rows) |>
  group_by(resp_kmeans_cluster) |>
  summarise(
    n = n(),
    age = mean(age),
    life_satisfaction = mean(life_satisfaction)
  ) |>
  activate(columns) |>
  group_by(trait) |>
  summarise()
#> Warning: Removed 5 stored analysis object(s) due to summarize: row_pca, column_pca, item_clusters, resp_hclust, resp_kmeans
#> Metadata columns are preserved.

m <- profile$matrix
dimnames(m) <- list(
  paste("cluster", profile$row_data$resp_kmeans_cluster),
  profile$col_data$trait
)

profile$row_data
#>   resp_kmeans_cluster   n      age life_satisfaction
#> 1                   1 126 45.53968          6.317460
#> 2                   2 137 44.18978          7.350365
#> 3                   3 125 36.18400          5.168000
round(m, 2)
#>           Agreeableness Conscientiousness Extraversion Neuroticism Openness
#> cluster 1          3.46              2.95         2.79        2.90     2.33
#> cluster 2          3.69              3.42         3.33        2.67     3.83
#> cluster 3          2.86              2.19         3.08        3.93     3.26
Personality traits are continuous and do not form natural clusters, so k-means simply cuts the cloud of respondents into regions. The profiles still make sense: typically one cluster is high on neuroticism, and it is the one with the lowest life satisfaction.
Managing stored analyses
list_analyses(tm)
#> [1] "row_pca"       "column_pca"    "item_clusters" "resp_hclust"
#> [5] "resp_kmeans"

check_analyses(tm)
#> Analysis 'row_pca': VALID (388 rows x 30 columns)
#> Analysis 'column_pca': VALID (388 rows x 30 columns)
#> Analysis 'item_clusters': VALID (388 rows x 30 columns)
#> Analysis 'resp_hclust': VALID (388 rows x 30 columns)
#> Analysis 'resp_kmeans': VALID (388 rows x 30 columns)

tm_small <- remove_analysis(tm, "resp_hclust")
list_analyses(tm_small)
#> [1] "row_pca"       "column_pca"    "item_clusters" "resp_kmeans"
remove_analysis(tm) without a name removes all of
them.
When stored analyses are dropped
A stored object describes the data it was computed on. Once rows or columns are removed, reordered, aggregated or transformed, it no longer matches, so tidymatrix removes it and warns. The metadata columns stay, because they are still correct for the rows and columns that remain.
tm_filtered <- tm |>
  activate(rows) |>
  filter(age >= 30)
#> Warning: Removed 5 stored analysis object(s) due to filter: row_pca, column_pca, item_clusters, resp_hclust, resp_kmeans
#> Metadata columns are preserved.

list_analyses(tm_filtered)
#> character(0)

tm_filtered |>
  activate(rows) |>
  select(respondent_id, row_pca_PC1, resp_kmeans_cluster)
#> # A tidymatrix: 305 x 30 matrix
#> # Active: rows
#> #
#> # Row data: 305 rows x 3 columns
#> # Column data: 30 rows x 10 columns
#> #
#> # Active data (rows):
#>      respondent_id row_pca_PC1 resp_kmeans_cluster
#> R001          R001   2.0329689                   3
#> R002          R002   2.5004478                   3
#> R003          R003   2.1131131                   1
#> R004          R004   2.1817306                   3
#> R005          R005  -0.7987357                   1
#> R006          R006   5.1128660                   3
Re-run the analysis on the filtered data if you need the full object again.
See also
- MDS, t-SNE and UMAP for other embeddings.
- Plotting and exporting for PCA plots and clustered heatmaps.